Graphic: Labwor Technologies
The thing you have to admit first
A bug means one of your beliefs about the system is false. That is the entire situation. If the code did what you think it does, it would be working, so somewhere in your mental model there is a sentence that is simply not true, and your job is to find out which one.
This sounds obvious and almost nobody behaves as though it is. The instinct under pressure is to defend the model instead of examining it: it cannot be the database, I only changed the styling, that worked yesterday. Every one of those sentences is a place you have decided not to look, and bugs live in exactly those places, because if you had already suspected them you would have already checked.
So the opening move is internal rather than technical. Before touching anything, name what you are assuming. If the problem is serious, write the assumptions down, one line each. That list is your search space, and you will be surprised how often the answer is already on it, sitting under a line you wrote confidently.
The second admission is about time. Debugging feels like it should be fast because the fix is usually small, and that expectation is what makes people skip steps. The fix is small. Finding it is not, and a method that looks slower for the first twenty minutes is almost always faster by the end of the hour.

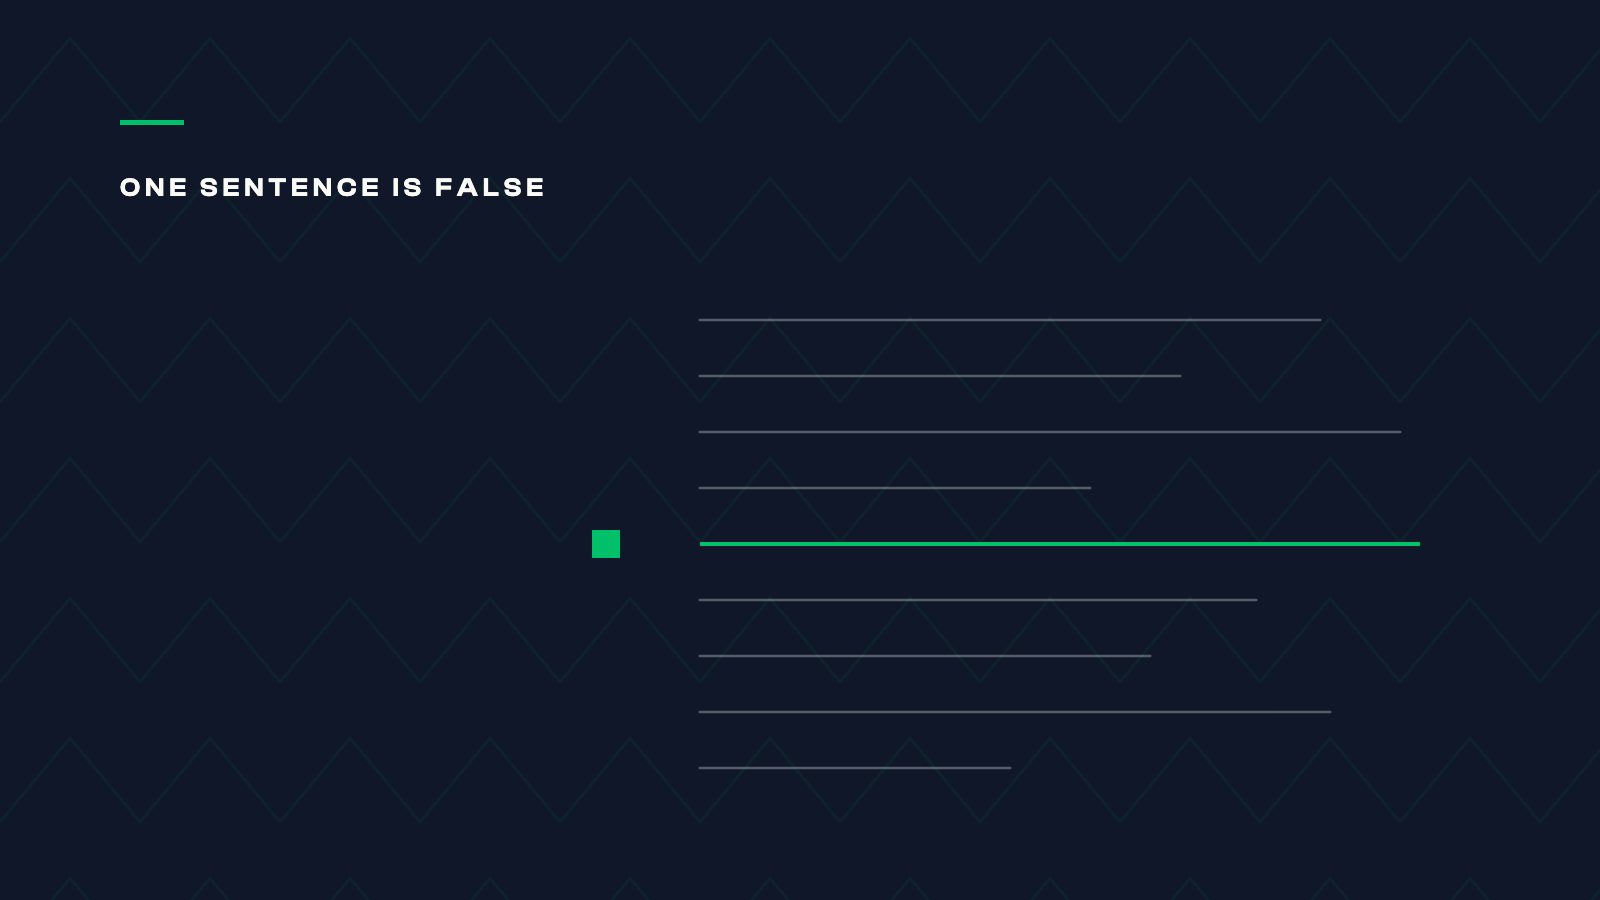
Each step throws away ground until only the false belief is left. The widths are illustrative, not measured.
Reproduce it, or you are guessing
You cannot fix what you cannot make happen on demand. Everything after this step is easier if you get this step right, and everything after it is theatre if you skip it.
The hardest reproduction I have dealt with came during on-call support for an Ozone deployment at a facility in Burundi. The report arrived by phone, from another country, describing a screen that had refused to cooperate, from a user standing in the middle of a working clinic with patients waiting. There was no stack trace and no screenshot. Half a day went into establishing what exactly had been clicked, in what order, by a user holding which role. Once that sequence was written down and I could trigger the failure myself, the actual fix took a fraction of the time.
That ratio is normal, and internalising it changes how you spend an afternoon. Treat the moment you can reliably trigger a bug as the moment the bug is mostly solved, and treat any fix applied without reproduction as a guess you have decided to deploy to real users.
Intermittent problems deserve their own note, because they defeat the naive version of this rule. If a failure happens one time in five, you must run it fifteen times before you believe a fix, and you must resist the enormous temptation to declare victory after two clean runs. We had a case on one of our own storefronts where cart creation would occasionally fail with no visible error at all. The cause turned out to be nothing in the cart code: the backend sits on a hosting tier that sleeps when idle, so the first request after a quiet period could take ten to fifteen seconds, and the front end had given up before the answer arrived. Every attempt to reproduce it during an active working session succeeded perfectly, which is precisely why it survived so long. The conditions that produced the bug were the conditions in which nobody was looking.
Read the actual error, then narrow the ground
Error messages are the cheapest information you will ever be given and they are routinely thrown away. People read the first line, decide they recognise the category, and start fixing something adjacent.
Read to the bottom. The useful part of a stack trace is often not the top frame but the point where execution crosses from your code into somebody else’s, or the second exception introduced after the words caused by. Read the file path and confirm it is the file you think it is. Read the line number and open that line, in that file, on that machine. When I was adding Billing, Insurance and LabTest frontend modules to a client’s OpenMRS instances in Botswana, most of the interface faults I chased were resolved by browser developer tools telling me the plain truth about a request I had assumed was fine. The information had been there the whole time. The bug was that I had not looked at it.
Once the error is read and the problem reproduces, cut the search space in half. This is the oldest tactic there is and it still outperforms cleverness, mostly because it does not depend on you being right about anything.
Halving works in more dimensions than people use. In code, remove or stub sections until the failure disappears, then restore the last thing you removed. In time, walk backwards through commits until you find the one where behaviour changed. In the stack, decide whether the fault is in the browser, the network, the application or the database, and prove which rather than assuming. In data, run the operation on one record instead of a thousand, then on the specific record that fails.
Four dimensions you can halve. Most people only ever use the first.
The infrastructure version of this saved me repeatedly while deploying OpenMRS on AWS with Docker, Ansible and Terraform. When something did not work, the layer being blamed was rarely the layer at fault. A successful apply tells you resources exist. It says nothing about whether the container inside them started, and the container starting says nothing about whether it could reach the database. Establishing which layer is lying to you is most of the diagnosis.
One hypothesis at a time
When you have narrowed enough to have a theory, write it as a sentence that could be proven false. Not the styling is broken, but this colour utility is not being generated because the token name does not match the naming convention.
That specific example is a recurring one across our own sites. Tailwind’s fourth version generates utilities from tokens declared in a theme block, and the naming rules are strict. Give a token a slightly wrong prefix and the class you wrote in your markup silently does nothing: no error, no warning, a successful build, and a page that looks wrong. Arbitrary values behave the same way when a file sits outside the content scan path. Bugs of this shape are dangerous precisely because every tool in the chain reports success, so a developer hunting for an error will never find one. Only a falsifiable statement gets you there. If this class is not being generated, it will be absent from the compiled stylesheet. Then go and look in the compiled stylesheet, and you will know in thirty seconds.
Testing one hypothesis at a time is also a discipline of restraint. If you have three theories, do not implement three fixes. You will not know which one worked, and you will have introduced two changes you do not understand into a system you already did not understand. Worse, if the symptom disappears you will stop, and the two mystery changes will stay in the codebase forever, quietly waiting.
Change one thing, and write down what you changed
Under pressure, debugging degrades into a sequence of half-remembered edits. After forty minutes in that state you no longer know what the code contains, what you have already tried, or what the original symptom actually looked like, and at that point you are not debugging, you are stirring.
Keep a running note. It does not need to be tidy. Time, what I believed, what I changed, what happened, two lines each. This does three separate jobs: it stops you repeating an experiment you already ran, it tells you when you have drifted away from the original symptom onto some other problem you discovered in passing, and it becomes the explanation you owe the client or the community afterwards.
Working in open source made me stricter about this. In the OpenMRS community a problem solved alone and in silence has half the value of the same problem written down where the next implementer can find it. I contributed to making the community Billing module configurable through JSON and XML files so that country implementers could change behaviour without redeploying code, and the documentation explaining why it works that way is now as load-bearing as the code. The same principle holds at the scale of a single afternoon’s bug. The note you write while confused is the artefact somebody else will thank you for.
Knowing when to stop
There are two kinds of stopping and both are skills that have to be practised, because neither comes naturally when you are close to something.
The first is stopping for fifteen minutes. Fixation is real, and there is a point past which additional staring produces nothing but a worse mood. Walk out, drink water, explain the problem aloud to somebody who does not work on it. Narrating forces you to state your assumptions in complete sentences, and roughly half the time you hear the false one leave your own mouth before the other person has said a word.
The second is stopping the investigation entirely. If a production system is down, a mitigation now beats a root cause in two hours: restart it, roll back, put up a notice, then find the cause with the pressure off and your judgement restored. And if the bug is genuinely small, intermittent and cosmetic, it is legitimate to write it down, leave it, and go do something worth more. Not every mystery has earned your afternoon.
The best debuggers I have worked with are not the fastest thinkers in the room. They are the ones most willing to be wrong out loud, in writing, one assumption at a time, until the system finally tells them something they did not expect. The bug is never hiding. It is sitting in the one place you were certain you did not need to check, waiting for you to run out of better ideas.
Frequently asked questions
What is the most effective method for debugging a production software issue?
Reproduce the problem reliably before anything else, since a fix applied without reproduction is a guess. Read the actual error message to the bottom rather than assuming you recognise it, then halve the search space, in the code, across time, through the stack, or in the data, until only a testable theory is left. Change one thing at a time and write down what you tried.
Why do intermittent bugs take so long to fix?
Because they defeat the normal reproduction rule. If a failure only shows up one time in five, you have to run the fix many times before trusting it, and the temptation to declare victory after two clean runs is enormous. Often the bug only appears under conditions nobody is watching for, such as a backend that has gone quiet after a period of no traffic and needs time to wake up.
How do you know when to stop debugging a problem?
There are two useful kinds of stopping. Step away for fifteen minutes when you are fixated and staring is producing nothing, and narrate the problem aloud to someone else. And if a production system is down, apply a mitigation first, a restart or a rollback, then investigate the real cause once the pressure is off. A small, intermittent, cosmetic bug can also legitimately be written down and left for later.